Knowledge is spread across PDFs, wikis and inboxes
03 / Services / GenAI / RAG
Vector Database IntegrationTurn knowledge into answers.
Semantic search, RAG and AI retrieval systems built on scalable vector database integrations, embeddings and LLM workflows.
01 / The problem
What usuallygets in the way.
Build AI applications grounded in your documents, with retrieval you can inspect, citations people can check, and evaluation built in.
Chatbot demos hallucinate on real questions
No way to tell whether answers are getting better or worse
02 / What I build
Capabilitiesin this service.
 01
Semantic Search & Retrieval
Build semantic search systems that return results based on meaning, similarity, and context, going beyond traditional keyword-based search experiences.
 02
RAG & Knowledge Pipelines
Connect vector databases with LLMs, retrievers, and knowledge sources to build RAG systems for document Q&A, AI assistants, and grounded responses.
 03
Indexing, Filtering & Metadata
Design vector indexes with metadata filtering, ranking logic, hybrid search, and efficient retrieval strategies for more precise and controllable search results.
 04
Backend & API Integration
Integrate vector search into your application stack using FastAPI, LangChain, Supabase, Node.js, or custom APIs for production-ready retrieval workflows.
 05
Performance, Scale & Optimization
Optimize vector systems for speed, accuracy, large-scale datasets, real-time updates, and low-latency retrieval across growing AI applications.
- Ingestion, chunking and retrieval tuned on your content
- Answers with citations and clear fallbacks
- An evaluation set and quality dashboard
03 / How it works
From documents to cited answers
A typical architecture for this kind of work. Scroll to follow the flow, or hover a stage for detail.
Documents
PDFs, pages and tickets, with access rules preserved.
Parsing
Text, tables and structure extracted cleanly.
Chunking
Sections sized for meaning, not a fixed character count.
Embeddings
Vectors that capture what each chunk is about.
Vector database
Fast similarity search with metadata filters.
Retrieval
Hybrid search and re-ranking pick the best context.
LLM
A prompt that answers only from retrieved context.
Answer + citations
Sources shown, so people can verify.
04 / In depth
The details.
Vector Database Integration Services
Build high-performance semantic search, RAG, and AI retrieval systems with scalable vector database integrations. I help businesses connect embeddings, vector search, and LLM workflows to create faster, smarter, and more context-aware AI applications.
My Expertise in Vector Database Integration
I specialize in building custom vector database integrations for businesses across legal tech, healthcare, e-commerce, SaaS, and other knowledge-driven industries. My solutions combine embeddings, semantic search, RAG pipelines, backend APIs, and scalable indexing strategies to help AI systems retrieve the right information with speed, relevance, and context.
- 🧬 Embeddings & Vectorization
- 🔎 Semantic Search & Retrieval
- 📚 RAG & Knowledge Pipelines
- 🗂 Indexing, Filtering & Metadata
- 🔗 Backend & API Integration
- ⚡ Performance, Scale & Optimization
Embeddings & Vectorization
Generate and manage vector embeddings for text, documents, images, and other unstructured data using modern embedding models and scalable ingestion workflows.
My Expertise in Data & AI Industry
From raw data to AI-powered decisions - I help businesses implement end-to-end machine learning workflows, analytics dashboards, and automation pipelines.
Hire MeRemote Data & AI Solutions
I’m a freelance Data Science and ML Engineer with 7+ years of experience transforming data into actionable insights. I specialize in building intelligent solutions, custom ML models, and scalable pipelines for startups and SMEs worldwide.
- United States (Remote Projects)
- Germany (AI Consultancy)
- EUROPE (Remote Projects)
- Remote - Available Worldwide
You Can find me here
As an independent Data & AI Engineer, I help companies unlock the full potential of their data. From predictive analytics to workflow automation, I offer strategic and technical support that drives real impact.
Book Free Consultation View Portfolio05 / Tech stack
Tools I usefor this work.
- LangChain
- LlamaIndex
- OpenAI
- Claude
- Pinecone
- FAISS
- FastAPI
06 / Related work
Proof,not promises.
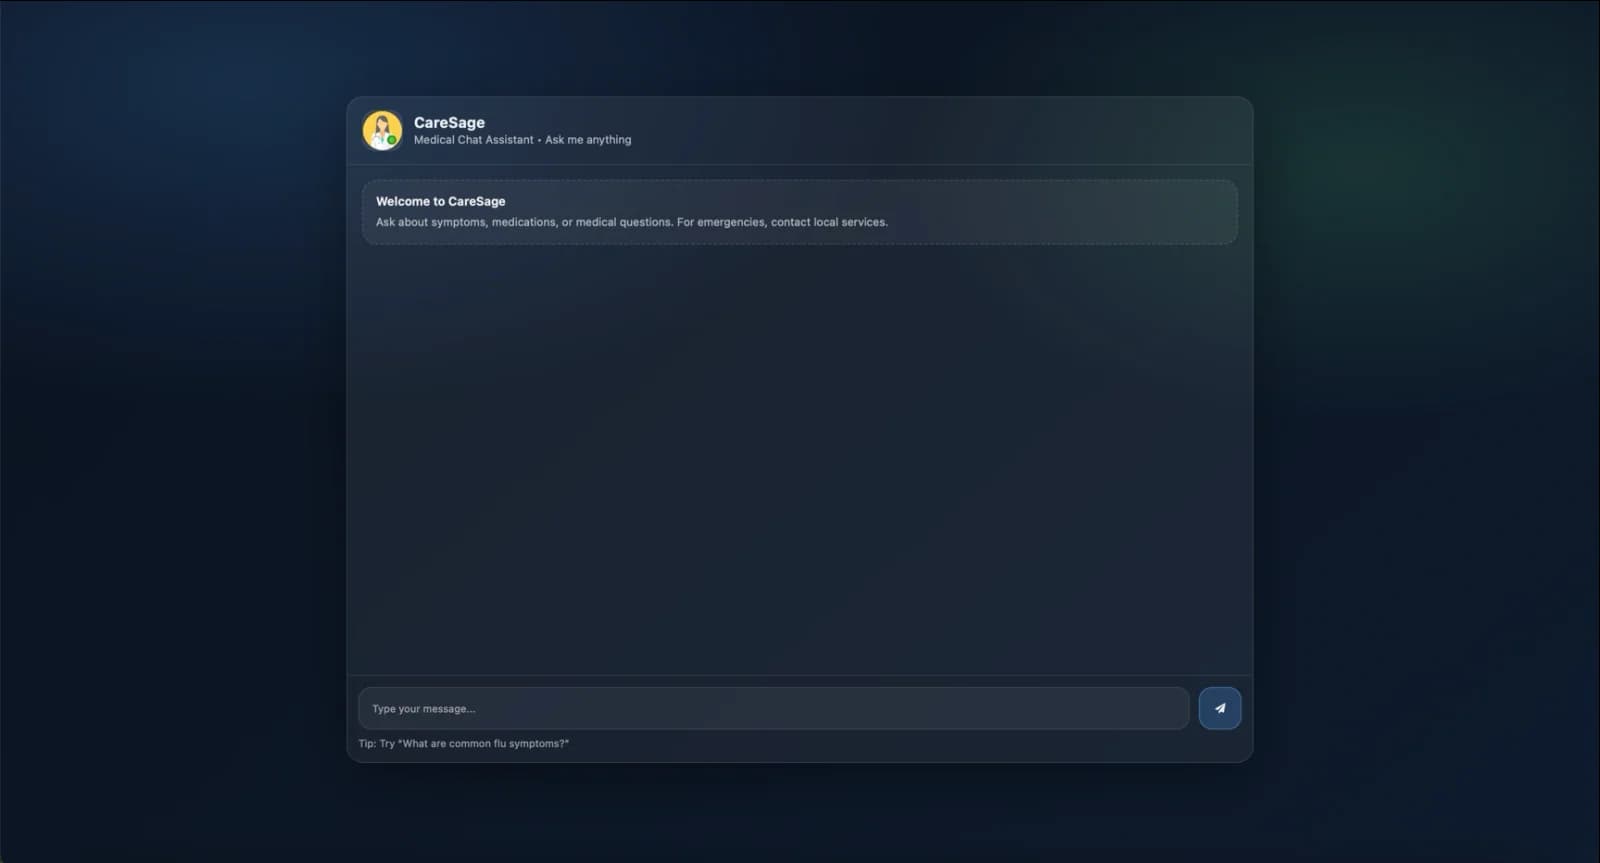
Project screenshotApplication interface
Medical RAG ChatbotLangChain + Pinecone + Flask
AI-Powered Medical Knowledge Assistant Retrieval-Augmented Generation (RAG) Chatbot
- Python
- LangChain
- Pinecone
- OpenAI
- +2
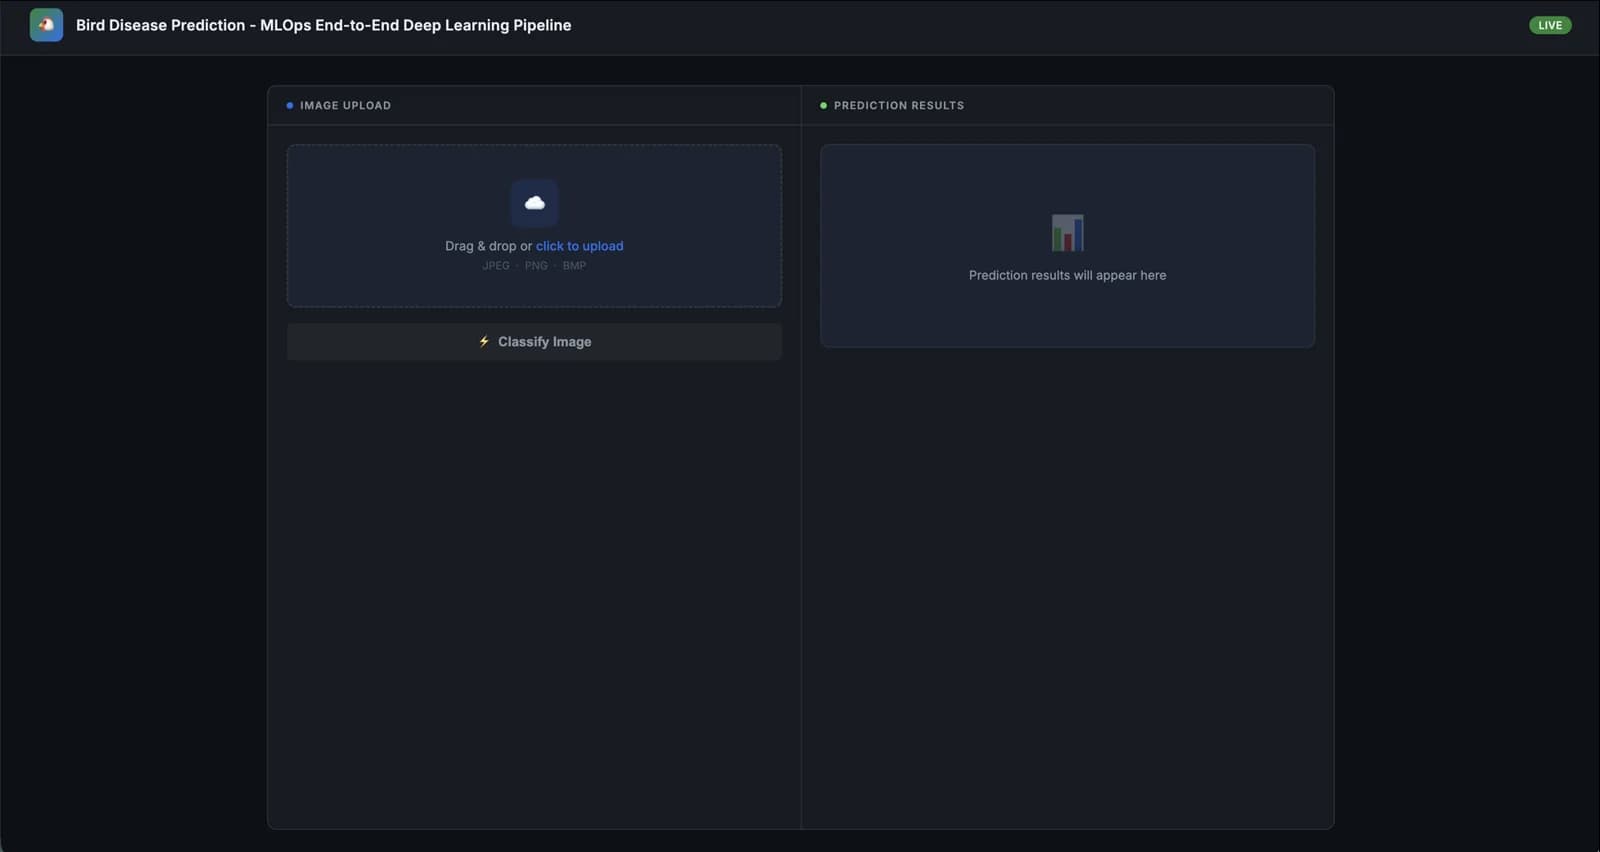
Project screenshotApplication interface
Bird Disease Classification (MLOps)
Built an end-to-end deep learning MLOps pipeline for bird disease classification using TensorFlow/Keras, PyTorch, OpenCV for image processing, FastAPI for model serving, and Docker for containerization. Implemented automated training pipelines, model versioning, and deployment workflows.
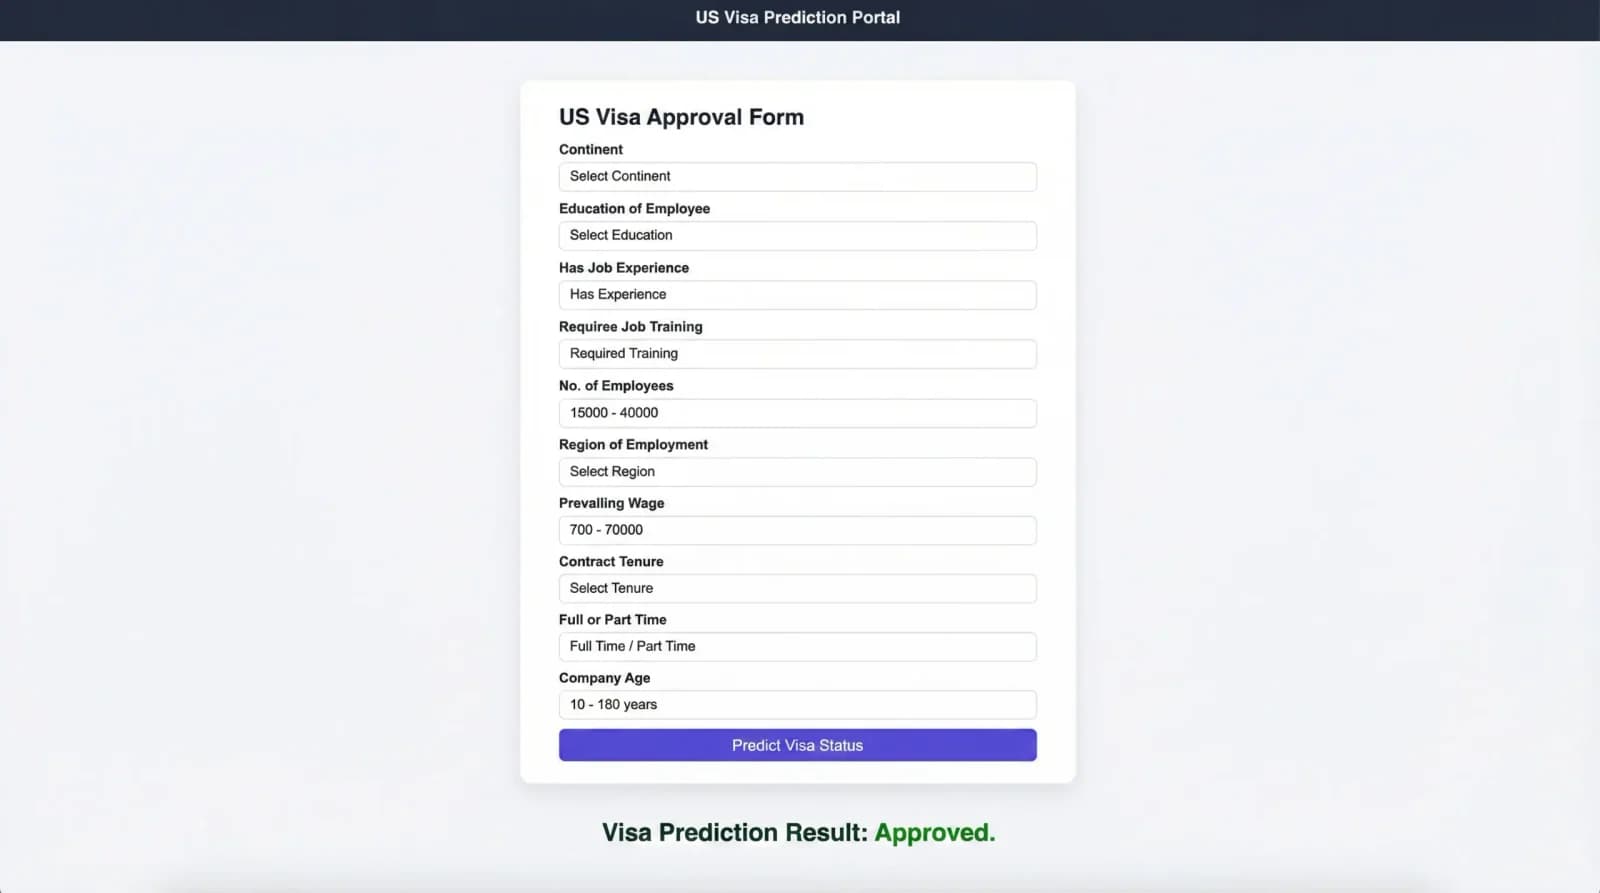
Project screenshotApplication interface
U.S. Visa Approval Prediction (MLOps)
Developed a complete MLOps pipeline for visa approval prediction using Python, FastAPI, Docker, AWS (EC2, ECR, S3), XGBoost, and CatBoost. Implemented automated model training, versioning, deployment, and monitoring with CI/CD integration for production-grade machine learning.
Uber Data Engineering ETL Project
- Python
- GCP
- BigQuery
- Mage.ai
Project overview
Uber Data Analytics Pipeline
Built a robust time-series forecasting solution with over 90% accuracy using Python and statistical modeling.It enabled a growing online retailer to better manage inventory, reduce overstock, and forecast seasonal demand shifts.
Project screenshotApplication interface
CareSage - RAG Medical Chatbot
Developed an intelligent medical chatbot using Retrieval-Augmented Generation (RAG) with Flask, LangChain, Pinecone vector database, OpenAI embeddings, and sentence-transformers. The system processes medical PDFs using PyPDF to provide accurate, context-aware responses for healthcare queries with citation support.
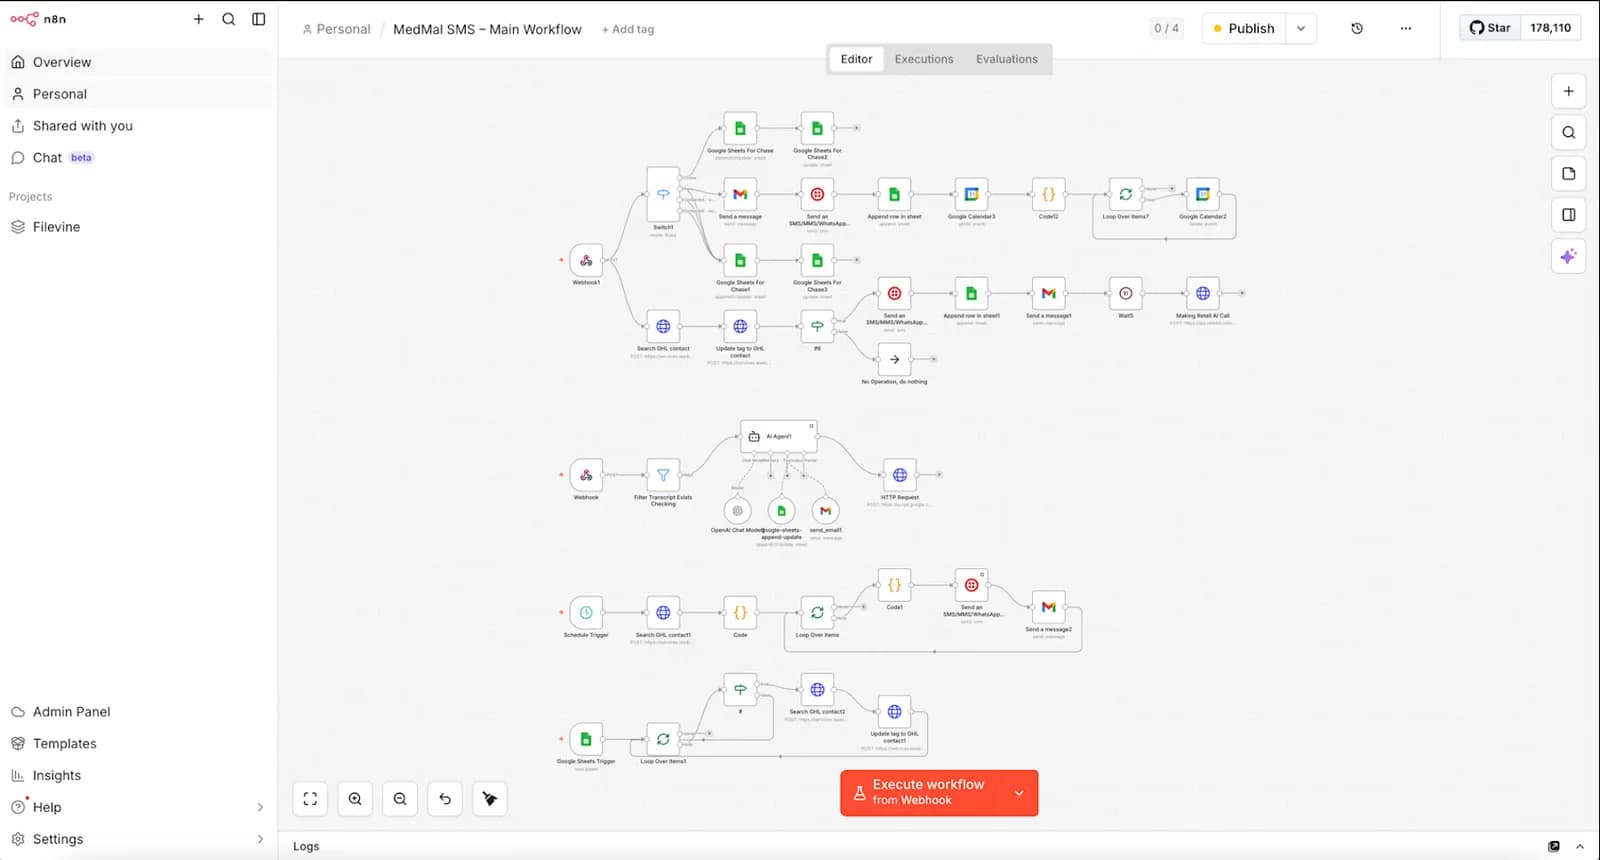
Project screenshotApplication interface
n8n Workflow Automation
Built 8 comprehensive automation workflows using n8n platform integrated with Retell AI, GoHighLevel, Twilio, OpenAI GPT-4, and PostgreSQL. Projects included AI Voice Agent for customer service, Multi-Channel Communication Hub, Lead Qualification System, CRM Sync Automation, Content Generation Pipeline, Customer Onboarding Workflow, Voice-Based Appointment Scheduler, and BI Reporting Dashboard.
07 / FAQ
Common questions.
What is a RAG application?
A RAG (retrieval-augmented generation) application answers questions from your own documents. It searches a vector index for the relevant passages and gives them to a language model, so answers are grounded in your content and can cite their sources.
Can RAG answer questions from medical or legal documents?
Yes, with citations so every answer can be checked. I have built a medical document assistant that answers healthcare questions from PDFs with source references. For legal and medical content, I add evaluation sets and refusal rules for questions the documents do not cover.
How do you reduce hallucinations in LLM applications?
Hallucinations drop when answers must come from retrieved sources, cite them, and decline when nothing relevant is found. I measure this with an evaluation set of real questions and run it on every change to prompts, models or data.
GenAI / RAG
Need Vector Database Integration?Let’s scope it together.
Tell me about the goal, the data and the constraints. I’ll reply with questions and a practical first step.