Every model release is a manual, risky event
03 / Services / LLMOps / MLOps
LLMOpsMove AI safely into production.
Production operations for LLM apps: evaluation, prompt versioning, observability, guardrails, cost control, and continuous improvement.
01 / The problem
What usuallygets in the way.
Evaluate, deploy and monitor models and LLM applications with tracing, versioning, cost controls and rollback plans.
Quality and cost are only noticed after complaints
Nobody can reproduce last month's model
02 / What I build
What you get.
- CI/CD for models and prompts, with evaluation gates
- Tracing, quality and cost dashboards
- Versioned artefacts, runbooks and rollback
03 / How it works
A loop, not a launch
A typical architecture for this kind of work. Scroll to follow the flow, or hover a stage for detail.
Model
A versioned model or prompt with its data lineage.
Evaluation
Automated checks against a fixed test set.
Deployment
Gated releases with canary and rollback.
Monitoring
Latency, cost, drift and quality in one view.
Feedback
Real usage flows back into the next evaluation.
04 / In depth
The details.
Shipping an LLM demo is easy; running one reliably in production is not. I put the operational layer around your LLM and RAG applications so they stay accurate, fast, safe, and affordable as they scale.
Evaluation & Testing
Automated eval suites (golden sets, LLM-as-judge, regression tests) wired into CI so every prompt or model change is measured before it ships.
Observability & Tracing
End-to-end tracing of prompts, retrievals, tool calls, tokens, latency, and cost - so you can see exactly why the model answered the way it did and fix it fast.
Guardrails & Cost Control
Input/output validation, PII and jailbreak protection, semantic caching, model routing, and token budgeting to cut spend without hurting quality.
05 / Tech stack
Tools I usefor this work.
- MLflow
- DVC
- LangSmith
- Evidently
- Docker
- GitHub Actions
- AWS
06 / Related work
Proof,not promises.
Project screenshotApplication interface
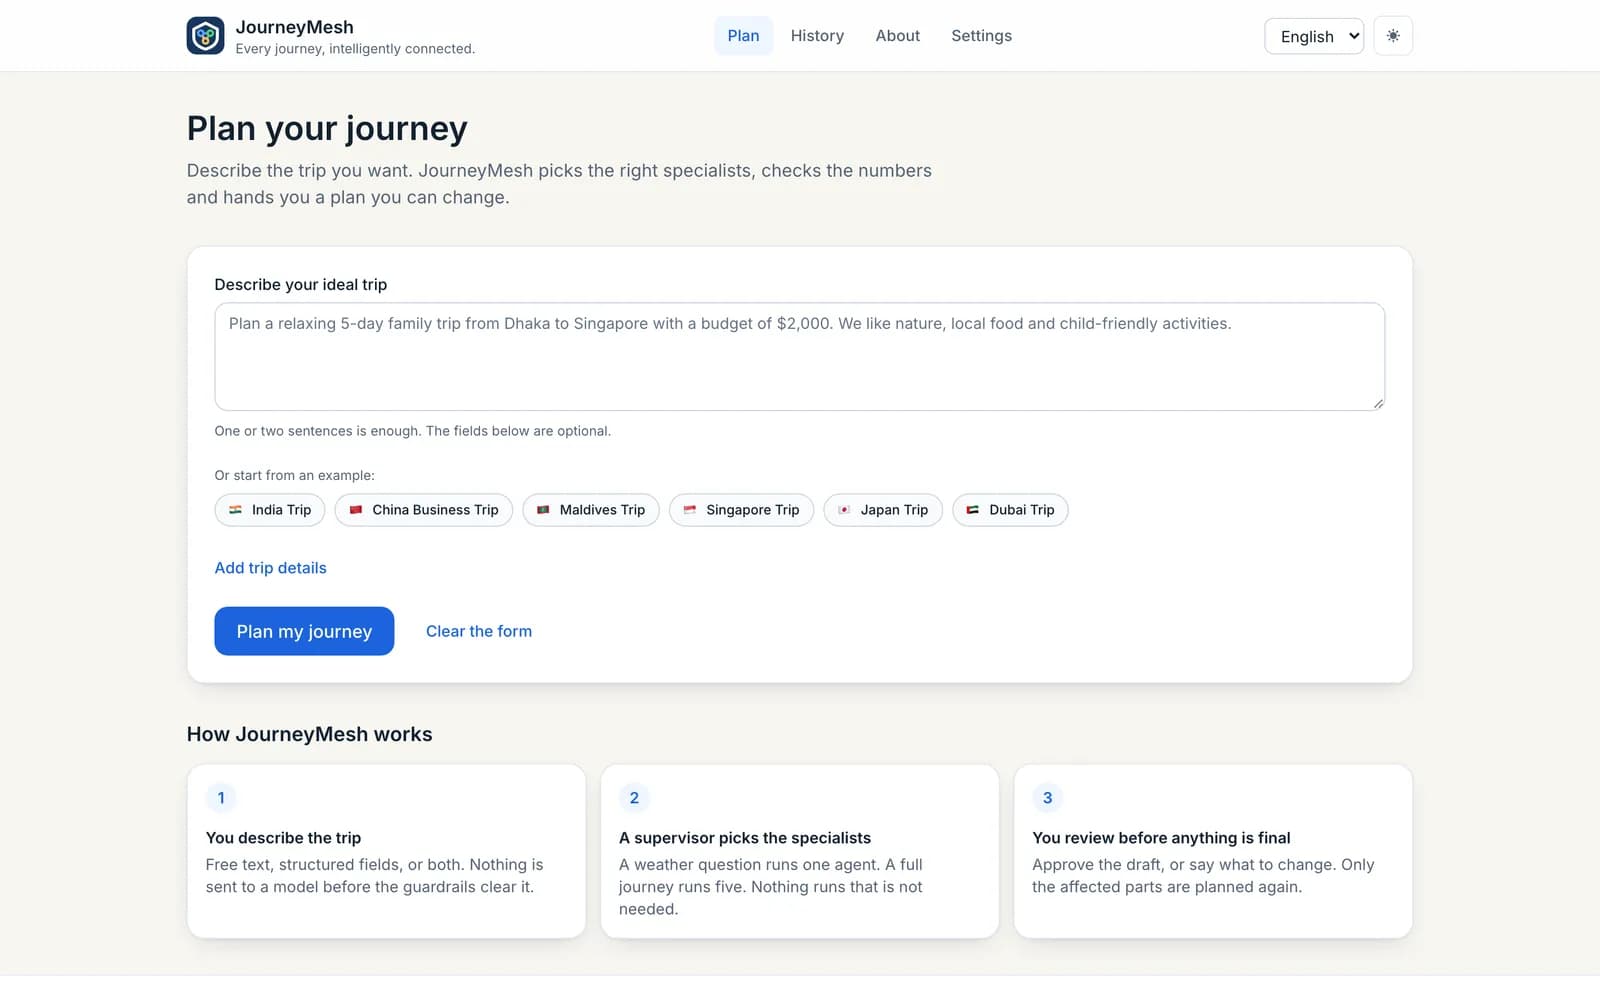
JourneyMeshMulti-Agent AI Travel Planner LangGraph + MCP + LLMOps
Supervisor-routed multi-agent travel planning with guardrails, evaluation and human review
- Python
- LangGraph
- LangChain
- MCP
- +8
Project screenshotApplication interface
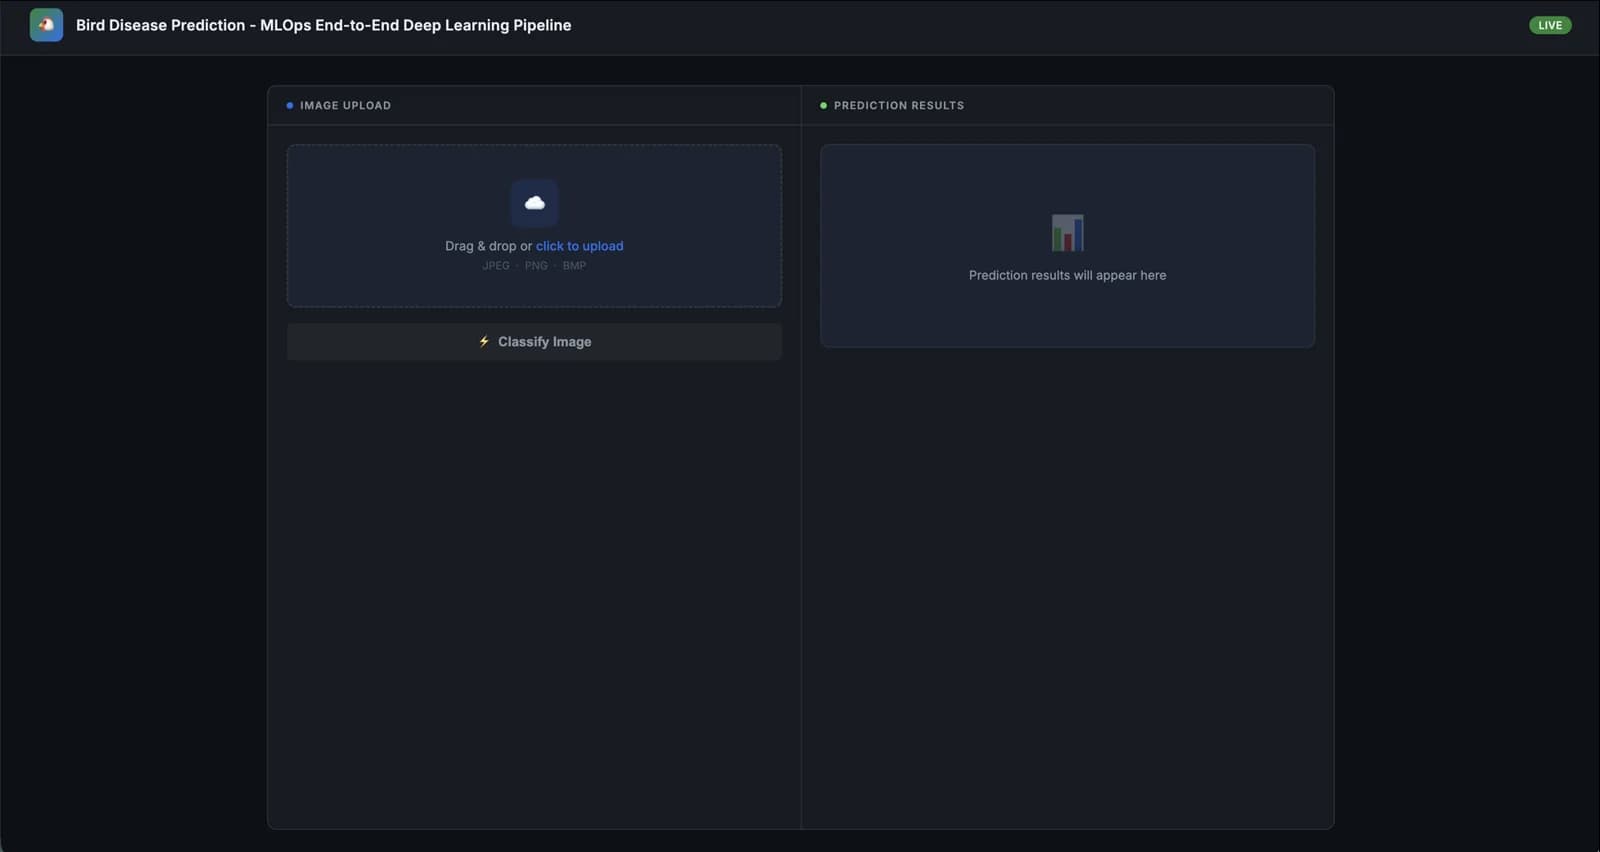
Bird Disease PredictionEnd-to-End MLOps Deep Learning
End-to-End MLOps Deep Learning Pipeline for Computer Vision CNN Training | Transfer Learning | Production Deployment
- Docker
- CI/CD
- REST
- Computer Vision
- +1
Project screenshotApplication interface
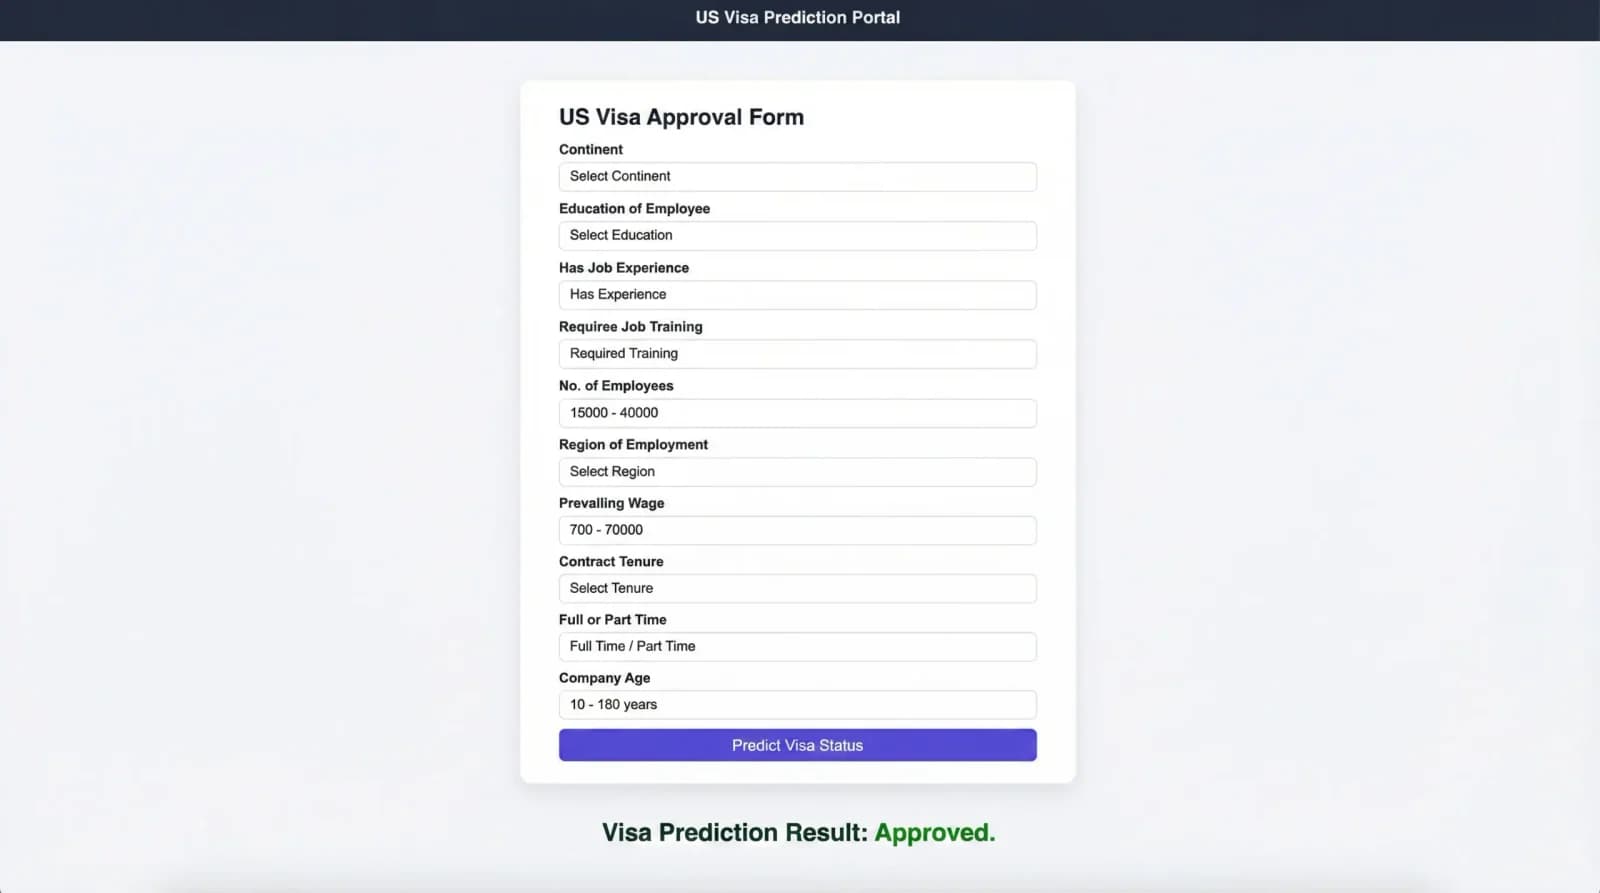
End-to-End MLOps ClassificationAWS + FastAPI + CI/CD
End-to-End MLOps Pipeline with CI/CD & Production Monitoring Data Ingestion → Training → Deployment → Monitoring
- FastAPI
- Docker
- CI/CD
- GitHub Actions
- +4
07 / FAQ
Common questions.
What is the difference between MLOps and LLMOps?
MLOps covers the training, deployment and monitoring of machine learning models. LLMOps applies the same discipline to language model applications, adding prompt versioning, evaluation sets, cost tracking and guardrails.
How do you monitor AI systems in production?
I track quality, latency, cost and errors for each model or prompt version with tools such as LangSmith, MLflow and Evidently. Alerts fire on drift or failures, and every release runs the evaluation set first.
LLMOps / MLOps
Need LLMOps?Let’s scope it together.
Tell me about the goal, the data and the constraints. I’ll reply with questions and a practical first step.